The problem
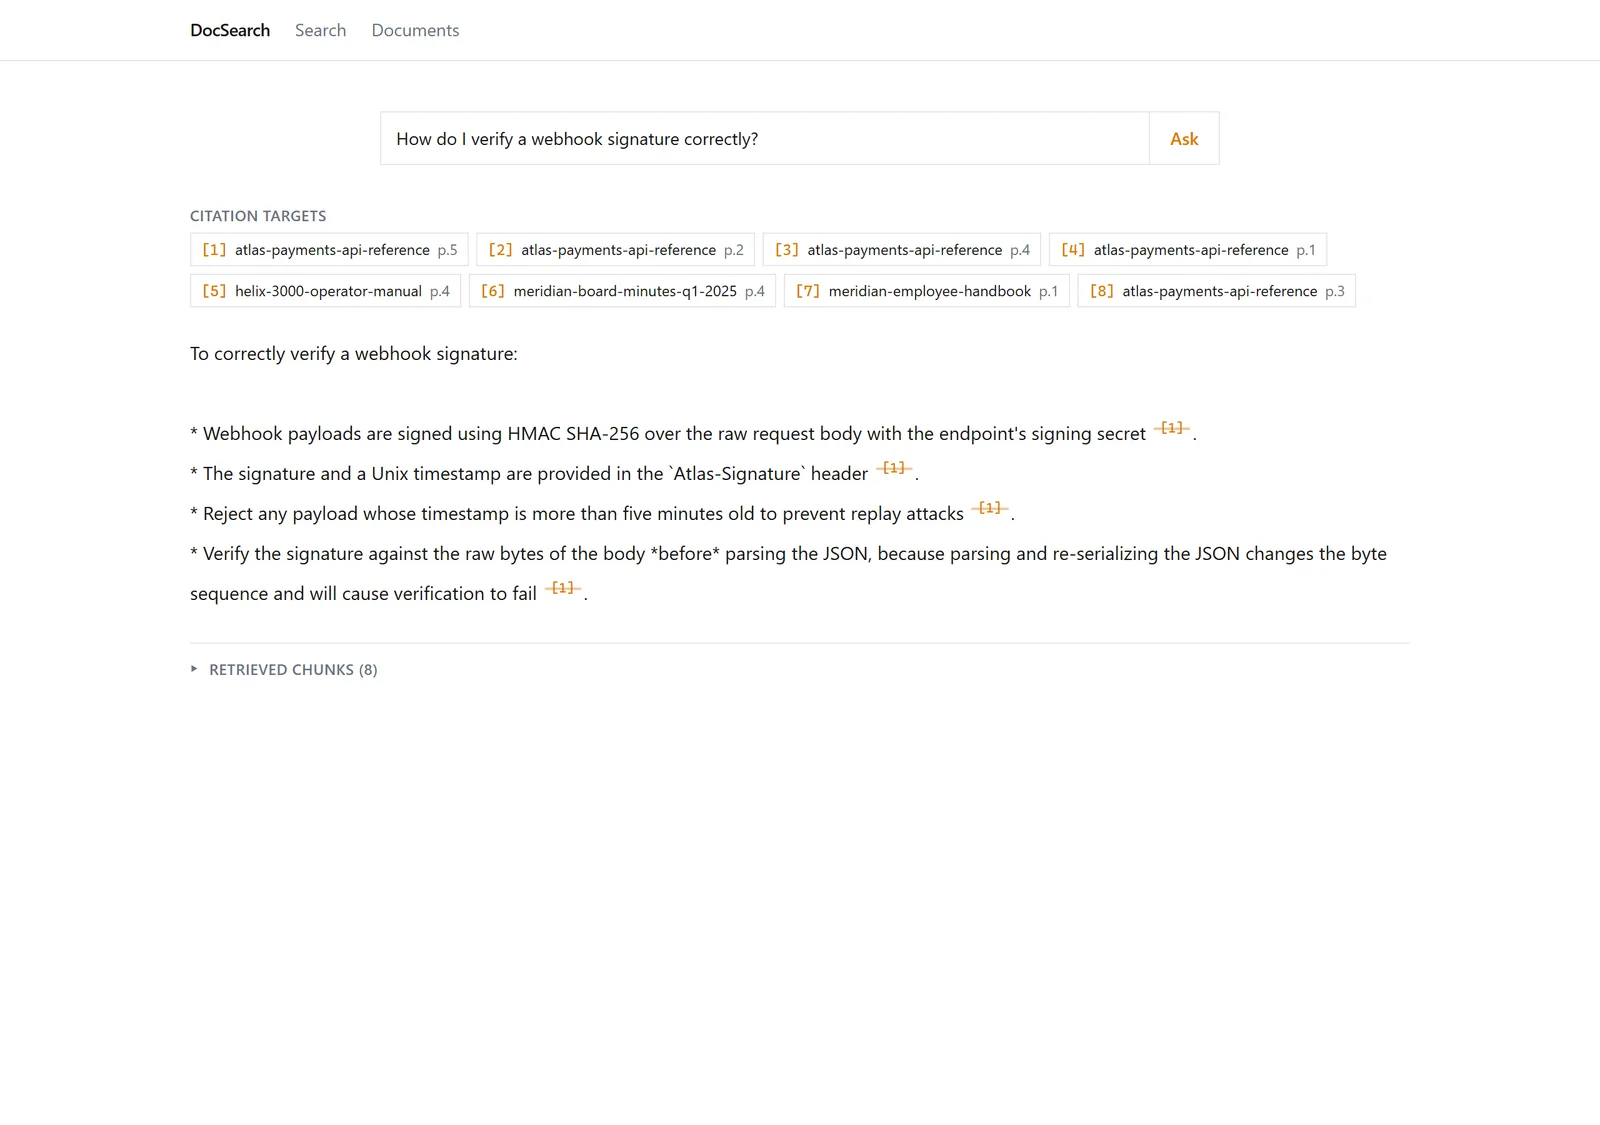
Question answering over documents is only useful if every claim can be traced to a source, and if the system refuses when the documents do not cover the question.
The approach
Hybrid retrieval: vector search and Postgres full-text search fused with Reciprocal Rank Fusion. Every claim in the streamed answer carries an inline citation to its source chunk. An evaluation harness measures retrieval and answer quality against a human-reviewed golden set. The pivot, Not Alone, answers a described struggle with the cited story of a holy person who fell the same way and was restored.
Results
- 91 human-reviewed evaluation questions.
- One of four LLM judges validated against human labels: Cohen's kappa 0.80 on a random sample.
- Answer correctness 52.4% on the dev split; 24 of 63 answerable questions get a refusal.
What broke and what I learned
- Three of four retrieval experiments did nothing, and the config was left unchanged rather than shipping an unmeasured win.
- The measurement was wrong three times: a truncated labelling UI, a contaminated unanswerable bucket, and a rubric with no answer for refusals. Each first looked like a system failure.